Input mix100%
Unused tools2,000 tok/call
run_tests ×328,800 input tok
read_file output4,200 output tok
read_file result; the log does not establish whether it was filtered. Bar lengths are not comparable because units and scopes differ; not all 28,800 tokens are avoidable. The causes can overlap, so do not sum them.5 steps77%
10 steps60%
20 steps36%
Stable prefixCACHE HIT
Full rewriteCACHE MISS
Baseline39,200 input tok
Illustrative fix~15,200 input tok
Stage 1 (0 tok)
Fast filter
Stage 2 (Judge)
Semantic check
`view_order_history` | `5월 10일`
`무선 이어폰`
`4567891230` | `한진택배`
`배송 중\|배송중` | Call `view_order_history(U002)` and report May 10 wireless earbuds shipping via Hanjin (`4567891230`) | | **`HF-ECOM5-T2`** (2/5) | `iamjoon/ecommerce-...` (`train[5]`) | `hybrid`
`view_user_profile` | `Gold`
`10%` | `할인 쿠폰\|쿠폰` | Retain `U002` from Turn 1, call `view_user_profile(U002)`, and report `Gold` tier + `10%` coupon | | **`HF-ECOM5-T3`** (3/5) | `iamjoon/ecommerce-...` (`train[5]`) | `hybrid`
`search_policy_info` | `7일`
`왕복 배송비` | `수령 후\|수령일`
`고객센터\|신청` | Call `search_policy_info(환불)` and state the 7-day post-receipt refund window and round-trip shipping fee | | **`HF-ECOM5-T4`** (4/5) | `iamjoon/ecommerce-...` (`train[5]`) | `hybrid`
`search_policy_info` | `반품` | `출고되기 전\|출고 전`
`출고 이후\|출고 후`
`주문취소 버튼\|주문내역` | Distinguish pre-shipment cancellation (order history button) from post-shipment return | | **`HF-ECOM5-T5`** (5/5) | `iamjoon/ecommerce-...` (`train[5]`) | `intent_only`
*(no tool)* | `담당자` | `직접 처리할 수 없\|직접 처리 불가`
`전달` | State that the AI agent cannot cancel payment directly and escalate to a human representative | | **`HF-ECOM2-T1`** (1/4) | `iamjoon/ecommerce-...` (`train[2]`) | `hybrid`
`show_cart` | `블루투스 이어폰`
`무선 마우스` | `1개;2개` | Call `show_cart(U001)` and report 1 Bluetooth earbud + 2 wireless mice | | **`HF-ECOM2-T2`** (2/4) | `iamjoon/ecommerce-...` (`train[2]`) | `hybrid`
`view_order_history`
`view_order_details` | `고성능 노트북`
`1,150,000원` | `1대;구매` | Retain `U001`, chain `view_order_history` → `view_order_details(O102)`, and confirm laptop purchase (`1,150,000원`) | | **`HF-ECOM2-T3`** (3/4) | `iamjoon/ecommerce-...` (`train[2]`) | `intent_only`
*(no tool)* | `담당자` | `기술적인 지원\|기술 지원`
`전달` | Identify repeated power-off as requiring technical support and escalate to the specialist team | | **`HF-ECOM2-T4`** (4/4) | `iamjoon/ecommerce-...` (`train[2]`) | `hybrid`
*(no tool)* | `카드 영수증`
`담당자` | `직접 처리할 수 없\|직접 처리 불가`
`전달` | State that card receipt issuance cannot be handled directly by the bot and forward to staff | | **`HF-DELIV-T1`** (1/1) | [`jjun123/delivery-app-...`](https://huggingface.co/datasets/jjun123/delivery-app-function-calling-datasets-korean) (`train[0]`) | `hybrid`
`create_delivery_order` | `14,900원;7,000원`
`21,900원;이서준`
`e2a4b1c9-...` | `관악구 관악로 1`
`준비 중\|준비중`
`담당자` | Summarize items, total (`21,900원`), recipient (`이서준`), order UUID, preparation status, and escalate ETA check | | **`HF-DFM14-T1`** (1/1) | [`schneiderkamplab/dfm14-...`](https://huggingface.co/datasets/schneiderkamplab/dfm14-ko-synthetic-tool-dialogue-r1) (`train[2]`) | `keyword_only`
`lookup_parcel`
`redirect_parcel` | `parcel-610`
`locker-16`
`redirect-610` | `변경 처리가 완료\|변경 완료` | Chain `lookup_parcel(10610, tracking-610)` → `redirect_parcel(locker-16, parcel-610)` and return `redirect-610` | | **`HF-CLINIC-T1`** (1/1) | `schneiderkamplab/dfm14-...` (`train[11]`) | `hybrid`
*(no tool)* | `병원 이름`
`서비스 종류` | `희망 날짜\|희망하는 날짜`
`모의 서비스\|가상`
`예약 가능 시간대` | Clarify that the service is a mock slot lookup (no real booking or medical advice) | | **`HF-KLAC-T1`** (1/1) | [`jihye-moon/klac_legal_aid...`](https://huggingface.co/datasets/jihye-moon/klac_legal_aid_counseling) (`train[1]`) | `hybrid`
*(no tool)* | `제34조;제4조`
`1년;4주;15시간` | `근로기준법`
`근로자퇴직급여 보장법`
`퇴직연금` | Cite Labor Standards Act Art. 34 & Retirement Benefit Act Art. 4 plus `< 1 year` and `< 15h/week` exclusions | | **`HF-KLAC-T2`** (1/1) | `jihye-moon/klac_legal_aid...` (`train[0]`) | `hybrid`
*(no tool)* | `최저임금법`
`제6조;무효;90%` | `3월\|3개월`
`수습` | Cite Minimum Wage Act Art. 6 (sub-minimum agreements void) and `90%` probation rule (`≤ 3 months`) | | **`HF-LABOR-T1`** (1/1) | [`seventy4/labor-counsel-qa`](https://huggingface.co/datasets/seventy4/labor-counsel-qa) (`train[34]`) | `hybrid`
*(no tool)* | `30일;30일분`
`통상임금;3개월` | `천재·사변\|부득이한 사유`
`예외` | State 30-day dismissal notice or `≥ 30 days` ordinary wage rule and `< 3 months` / force-majeure exceptions | | **`HF-OSCE-T1`** (2/2) | [`nwirandx/Korean-OSCE-...`](https://huggingface.co/datasets/nwirandx/Korean-OSCE-history-taking-dialogues) (`sessions[0..9]`) | `hybrid`
*(no tool)* | `김서현`
`1984년 5월 23일`
`20일;15분;20분;30분` | `과거력 없음\|과거력은 없`
`어지럽고\|어지러움`
`숨이 차\|호흡곤란` | Summarize 9 turns of clinical intake (patient info, 20-day onset, 15–20m → >30m progression, no past history, dizziness/dyspnea) | --- ## 4. Reviewing & designing a 10-point Rubric (5 axes × 0–2 points = 10 points max) Unanchored 1–10 scales drift between judge runs. Instead, decompose the 10-point score into **5 orthogonal axes × 0 / 1 / 2 points = 10 points max**. Separating **current-turn fact/slot accuracy (Axis 2)** from **multi-turn context retention (Axis 3)** and **tool/policy compliance (Axis 4)** pinpoints exactly which optimization caused a regression: | Rubric axis (5 Axes × 2 pts = 10 pts) | 0 pts (Fail — critical defect) | 1 pt (Partial) | 2 pts (Pass — full credit) | What it guards against | |---|---|---|---|---| | **1. Intent & core resolution**
(`intent_and_resolution`) | Misreads user intent or reaches a conclusion contrary to `expected_intent` | Captures intent but omits part of the required resolution or next step | Fully satisfies `expected_intent` regardless of phrasing | Semantic correctness when wording differs (`intent_only` / `hybrid`) | | **2. Fact, slot & numerical accuracy**
(`fact_and_slot_accuracy`) | Drops/distorts required IDs, numbers, dates, or statutes, or hallucinates facts | Core facts hold, but secondary numbers or conditions are vague | States all required keywords, numbers, IDs, and statutes accurately | Slot/number loss during BPE or prompt compression (`keyword` / `hybrid`) | | **3. Multi-turn context & state retention**
(`multiturn_context_retention`) | Forgets constraints or IDs from `prior_turns_context`, contradicting or re-asking | Partially recalls prior turns or links context loosely | Consistently retains user IDs, planted constraints, and state across turns | Memory loss after `/compact` or observation masking | | **4. Tool selection & policy guardrails**
(`tool_and_policy_compliance`) | Skips required tools and fabricates results, or violates `must_not_include` / policy | Obeys safety boundaries but makes redundant tool calls or minor format errors | Calls the right tools (or escalates out-of-scope actions) and obeys all policies | Over-pruned tool schemas or weakened guardrail prompts | | **5. Concise completeness (Verbosity guard)**
(`concise_completeness`) | Omits essential details so the user must ask again, or produces broken text | Complete but padded with repetitive greetings, apologies, or filler | **Complete, actionable, and concise — awards full marks to shorter answers** | **Prevents LLM judges from favoring bloated replies** | > **Recommended pass threshold:** A turn passes (`PASS`) only when all deterministic checks succeed **and** the 5-axis rubric total is **≥ 8 / 10** with no `0`-point axis. --- ## 5. Runnable Python `.xlsx` / `.csv` generator & evaluator (`examples/golden_dataset_tool.py`) [`examples/golden_dataset_tool.py`](https://github.com/dotnetpower/agent-tokenomics/blob/main/examples/golden_dataset_tool.py) uses only the Python standard library to generate a native two-sheet Microsoft Excel workbook ([`examples/sample-golden-dataset.xlsx`](https://github.com/dotnetpower/agent-tokenomics/raw/main/examples/sample-golden-dataset.xlsx): `Golden_Dataset` + `Rubric_Criteria` 10-point guide) and a `utf-8-sig` CSV ([`examples/sample-golden-dataset.csv`](https://github.com/dotnetpower/agent-tokenomics/blob/main/examples/sample-golden-dataset.csv)), evaluate all 16 Hugging Face single-turn and multi-turn rows directly from `.xlsx` or `.csv`, and print the 10-point LLM-as-a-Judge prompt: ```bash # 1. Generate the two-sheet Excel workbook (.xlsx) and UTF-8 BOM CSV (.csv) python3 examples/golden_dataset_tool.py --write-sample # 2. Evaluate Baseline vs. Candidate directly from the .xlsx workbook python3 examples/golden_dataset_tool.py --eval examples/sample-golden-dataset.xlsx # 3. Print the 10-point LLM-as-a-Judge rubric prompt for a 5-turn Hugging Face case (HF-ECOM5-T5) python3 examples/golden_dataset_tool.py --print-judge-prompt HF-ECOM5-T5 ``` ### Sample evaluation output (`examples/sample-golden-dataset.xlsx`, 16 rows) ```text case_id turn hf_dataset base_ok cand_ok base_tok cand_tok delta rubric -------------------------------------------------------------------------------------------------------- HF-ECOM5-T1 1 iamjoon/ecommerce-function-calli PASS PASS 4,200 2,350 -44.0% 10/10 HF-ECOM5-T2 2 iamjoon/ecommerce-function-calli PASS PASS 5,800 3,100 -46.6% 10/10 HF-ECOM5-T3 3 iamjoon/ecommerce-function-calli PASS PASS 7,400 3,850 -48.0% 10/10 HF-ECOM5-T4 4 iamjoon/ecommerce-function-calli PASS PASS 9,100 4,500 -50.5% 10/10 HF-ECOM5-T5 5 iamjoon/ecommerce-function-calli PASS PASS 10,800 4,950 -54.2% 10/10 HF-ECOM2-T1 1 iamjoon/ecommerce-function-calli PASS PASS 4,100 2,200 -46.3% 10/10 HF-ECOM2-T2 2 iamjoon/ecommerce-function-calli PASS PASS 6,900 3,600 -47.8% 10/10 HF-ECOM2-T3 3 iamjoon/ecommerce-function-calli PASS PASS 8,300 4,100 -50.6% 10/10 HF-ECOM2-T4 4 iamjoon/ecommerce-function-calli PASS PASS 9,600 4,450 -53.6% 10/10 HF-DELIV-T1 1 jjun123/delivery-app-function-ca PASS PASS 12,400 6,800 -45.2% 10/10 HF-DFM14-T1 1 schneiderkamplab/dfm14-ko-synthe PASS PASS 5,400 2,900 -46.3% 10/10 HF-CLINIC-T1 1 schneiderkamplab/dfm14-ko-synthe PASS PASS 4,900 2,700 -44.9% 10/10 HF-KLAC-T1 1 jihye-moon/klac_legal_aid_counse PASS PASS 6,400 3,300 -48.4% 10/10 HF-KLAC-T2 1 jihye-moon/klac_legal_aid_counse PASS PASS 5,900 3,100 -47.5% 10/10 HF-LABOR-T1 1 seventy4/labor-counsel-qa PASS PASS 5,200 2,850 -45.2% 10/10 HF-OSCE-T1 2 nwirandx/Korean-OSCE-history-tak PASS PASS 9,400 4,600 -51.1% 10/10 -------------------------------------------------------------------------------------------------------- Pass rate : Baseline 16/16 (100.0%) -> Candidate 16/16 (100.0%) Mean rubric score : Baseline 9.62/10 -> Candidate 10.00/10 Total tokens : Baseline 115,800 -> Candidate 59,350 (-48.7%) Cost-of-Pass (tok) : Baseline 7,238 tok/pass -> Candidate 3,709 tok/pass Decision : KEEP (Quality held & tokens reduced) ``` --- ## Further reading (papers) - [Cost-of-Pass: An Economic Framework for Evaluating Language Models](https://arxiv.org/abs/2504.13359) — preprint 2025. Evaluates models by expected cost per successful task (`Cost-of-Pass`) rather than per-call price alone. - [$\tau$-bench: A Benchmark for Tool-Agent-User Interaction in Real-World Domains](https://arxiv.org/abs/2406.12045) — preprint 2024. Evaluates multi-turn tool calls and policy compliance across repeat trials (`pass^k`). - [AI Agents That Matter](https://arxiv.org/abs/2407.01502) — preprint 2024. Establishes joint cost-and-accuracy reporting and anti-contamination practices for agent benchmarks. - [Adding Error Bars to Evals: A Statistical Approach to Language Model Evaluations](https://arxiv.org/abs/2411.00640) — preprint 2024. Computes paired confidence intervals and sample-size requirements for evaluations. - [LongMemEval: Benchmarking Chat Assistants on Long-Term Interactive Memory](https://arxiv.org/abs/2410.10813) — ICLR 2025. Benchmarks multi-turn fact retention and knowledge updates across long sessions. --- ## Case study: TokenEconomizer (agent-tokenomics/case-tokeneconomizer.md) Canonical URL:
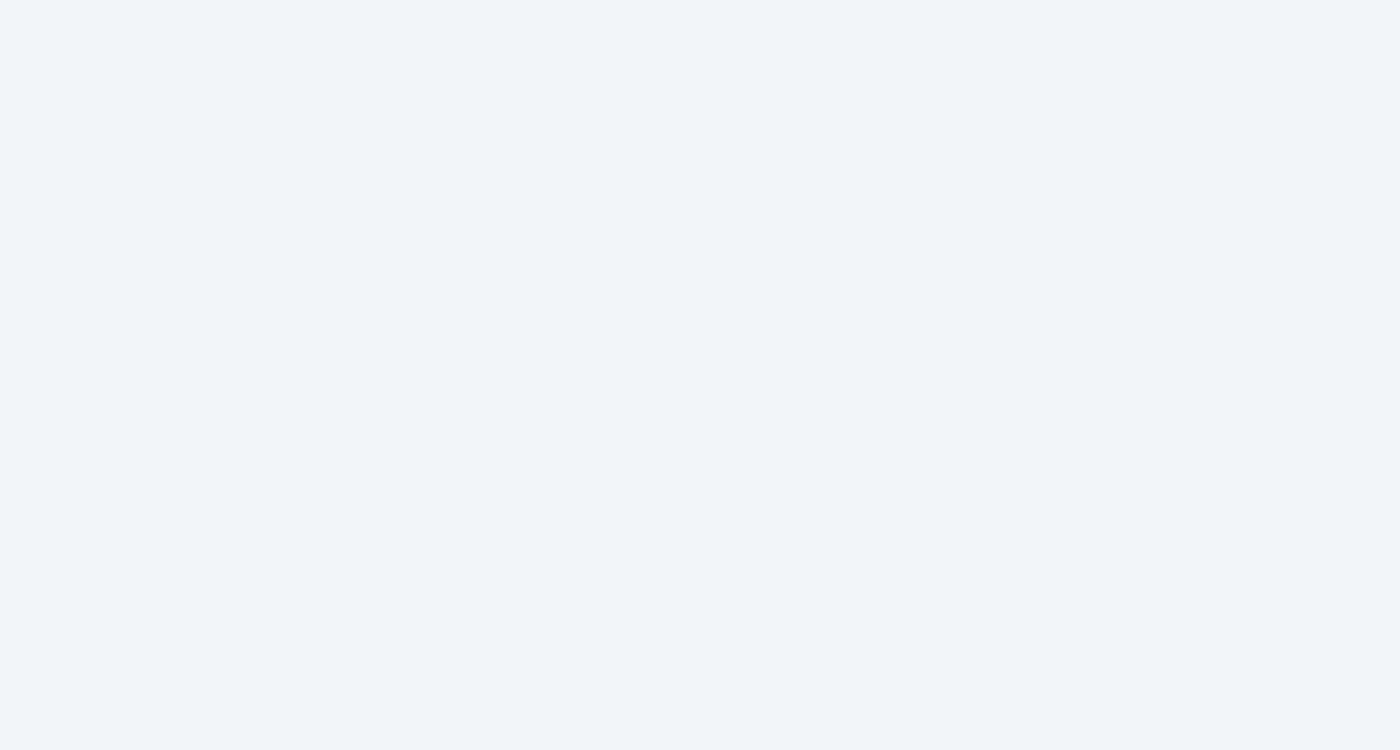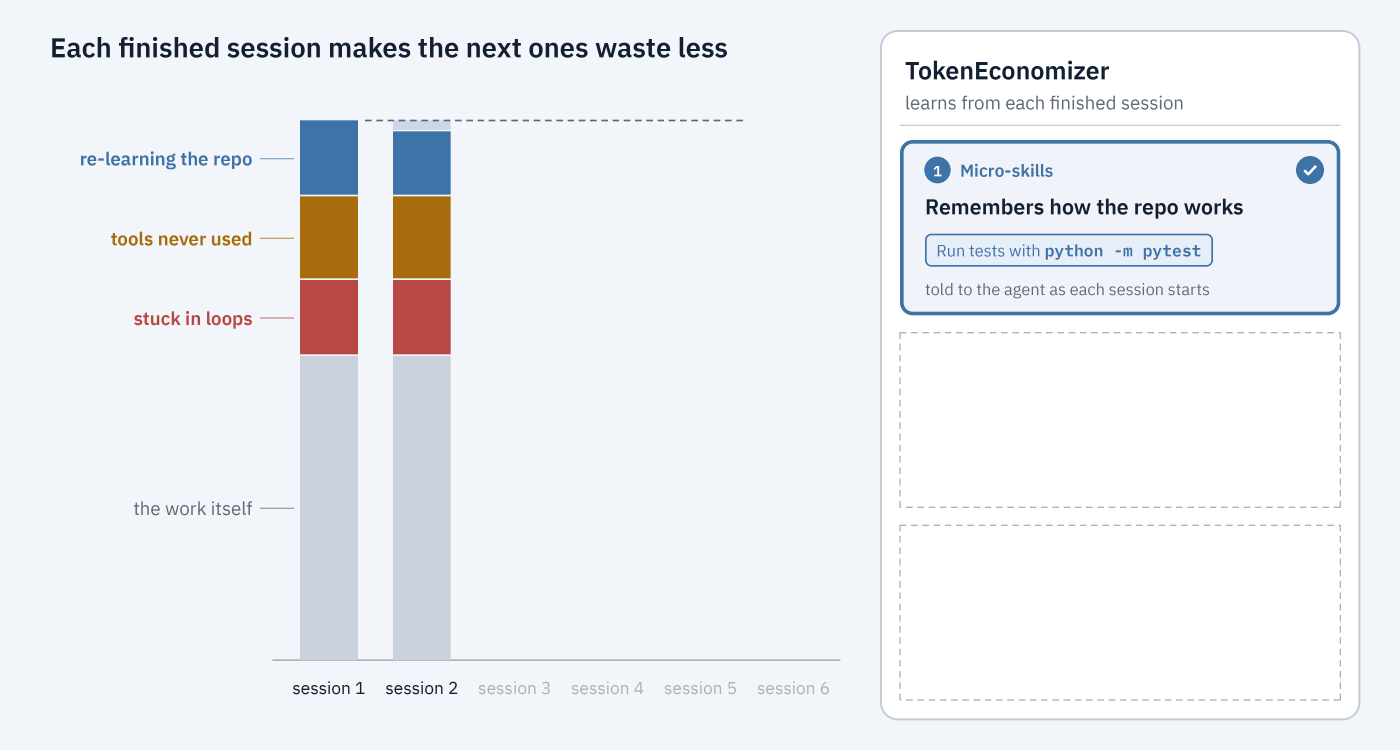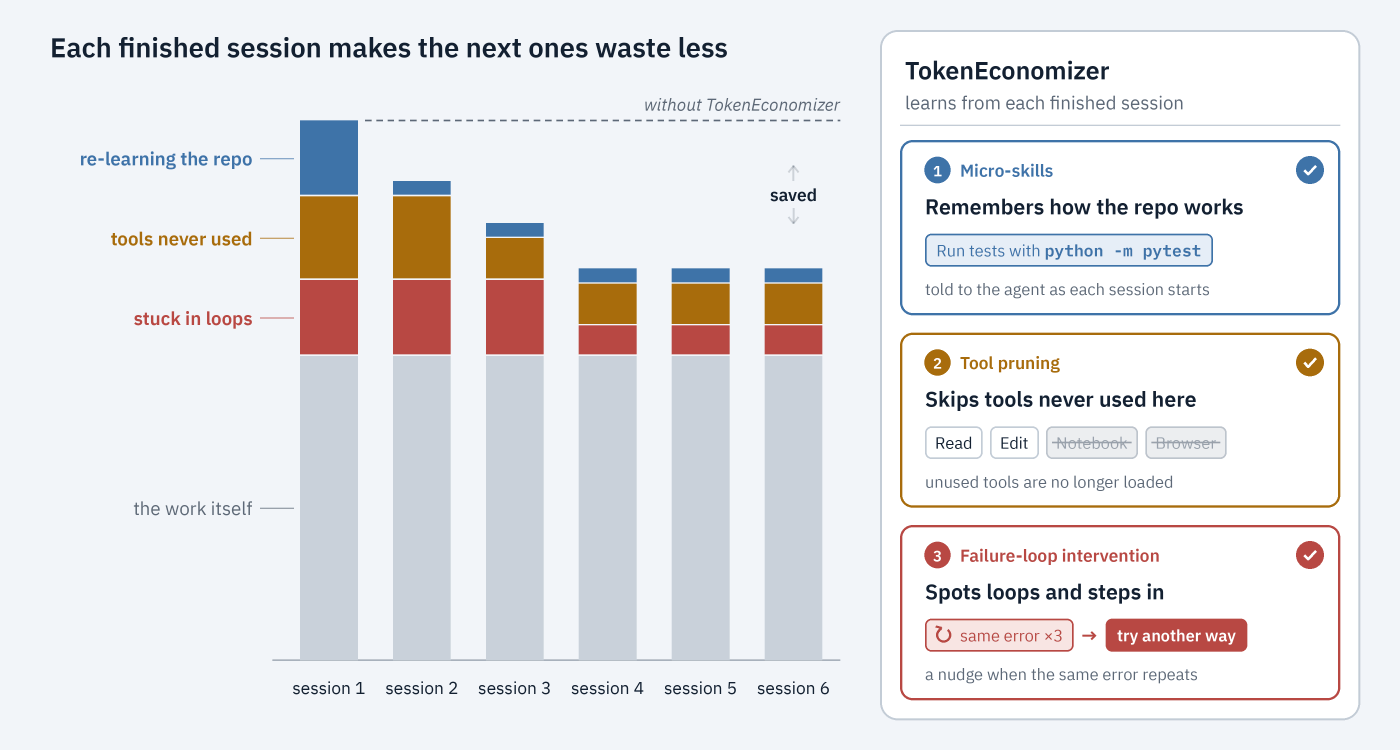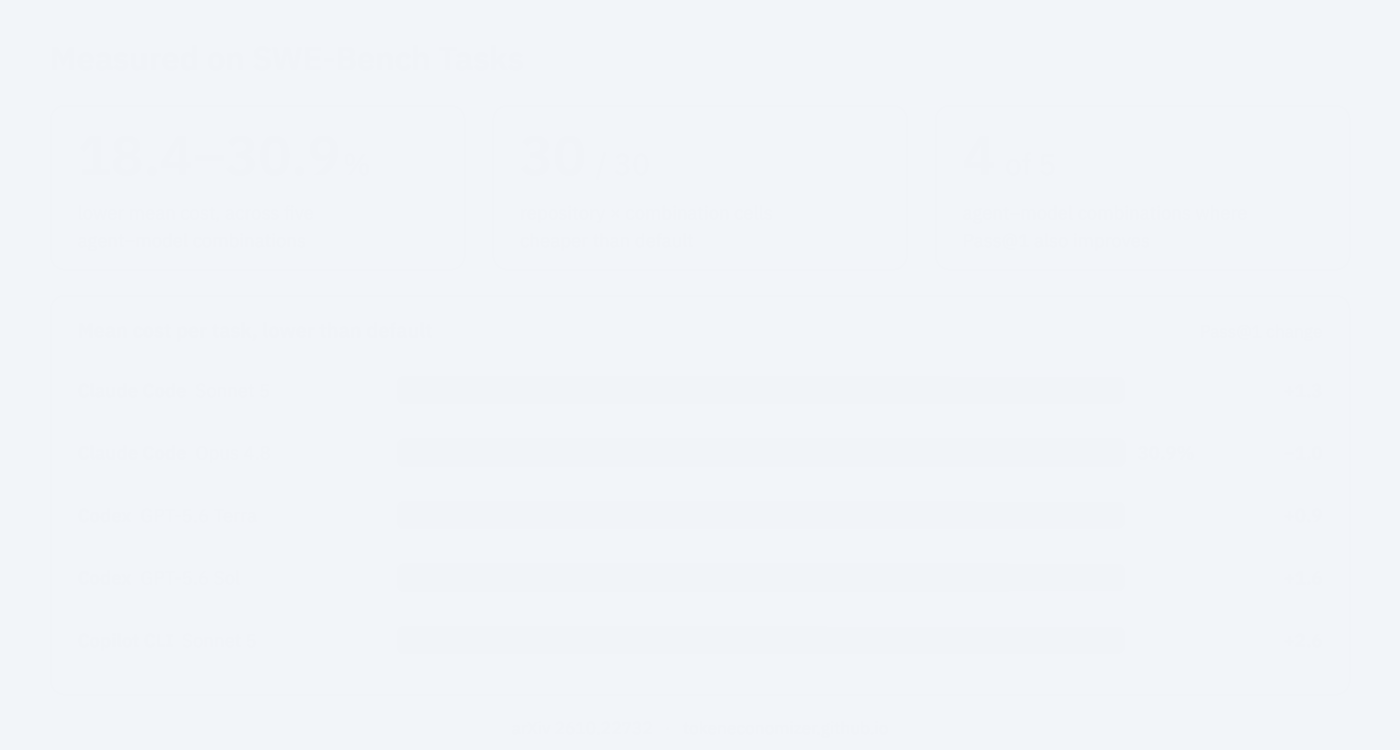
Repo facts
Tool selection
Failure handling
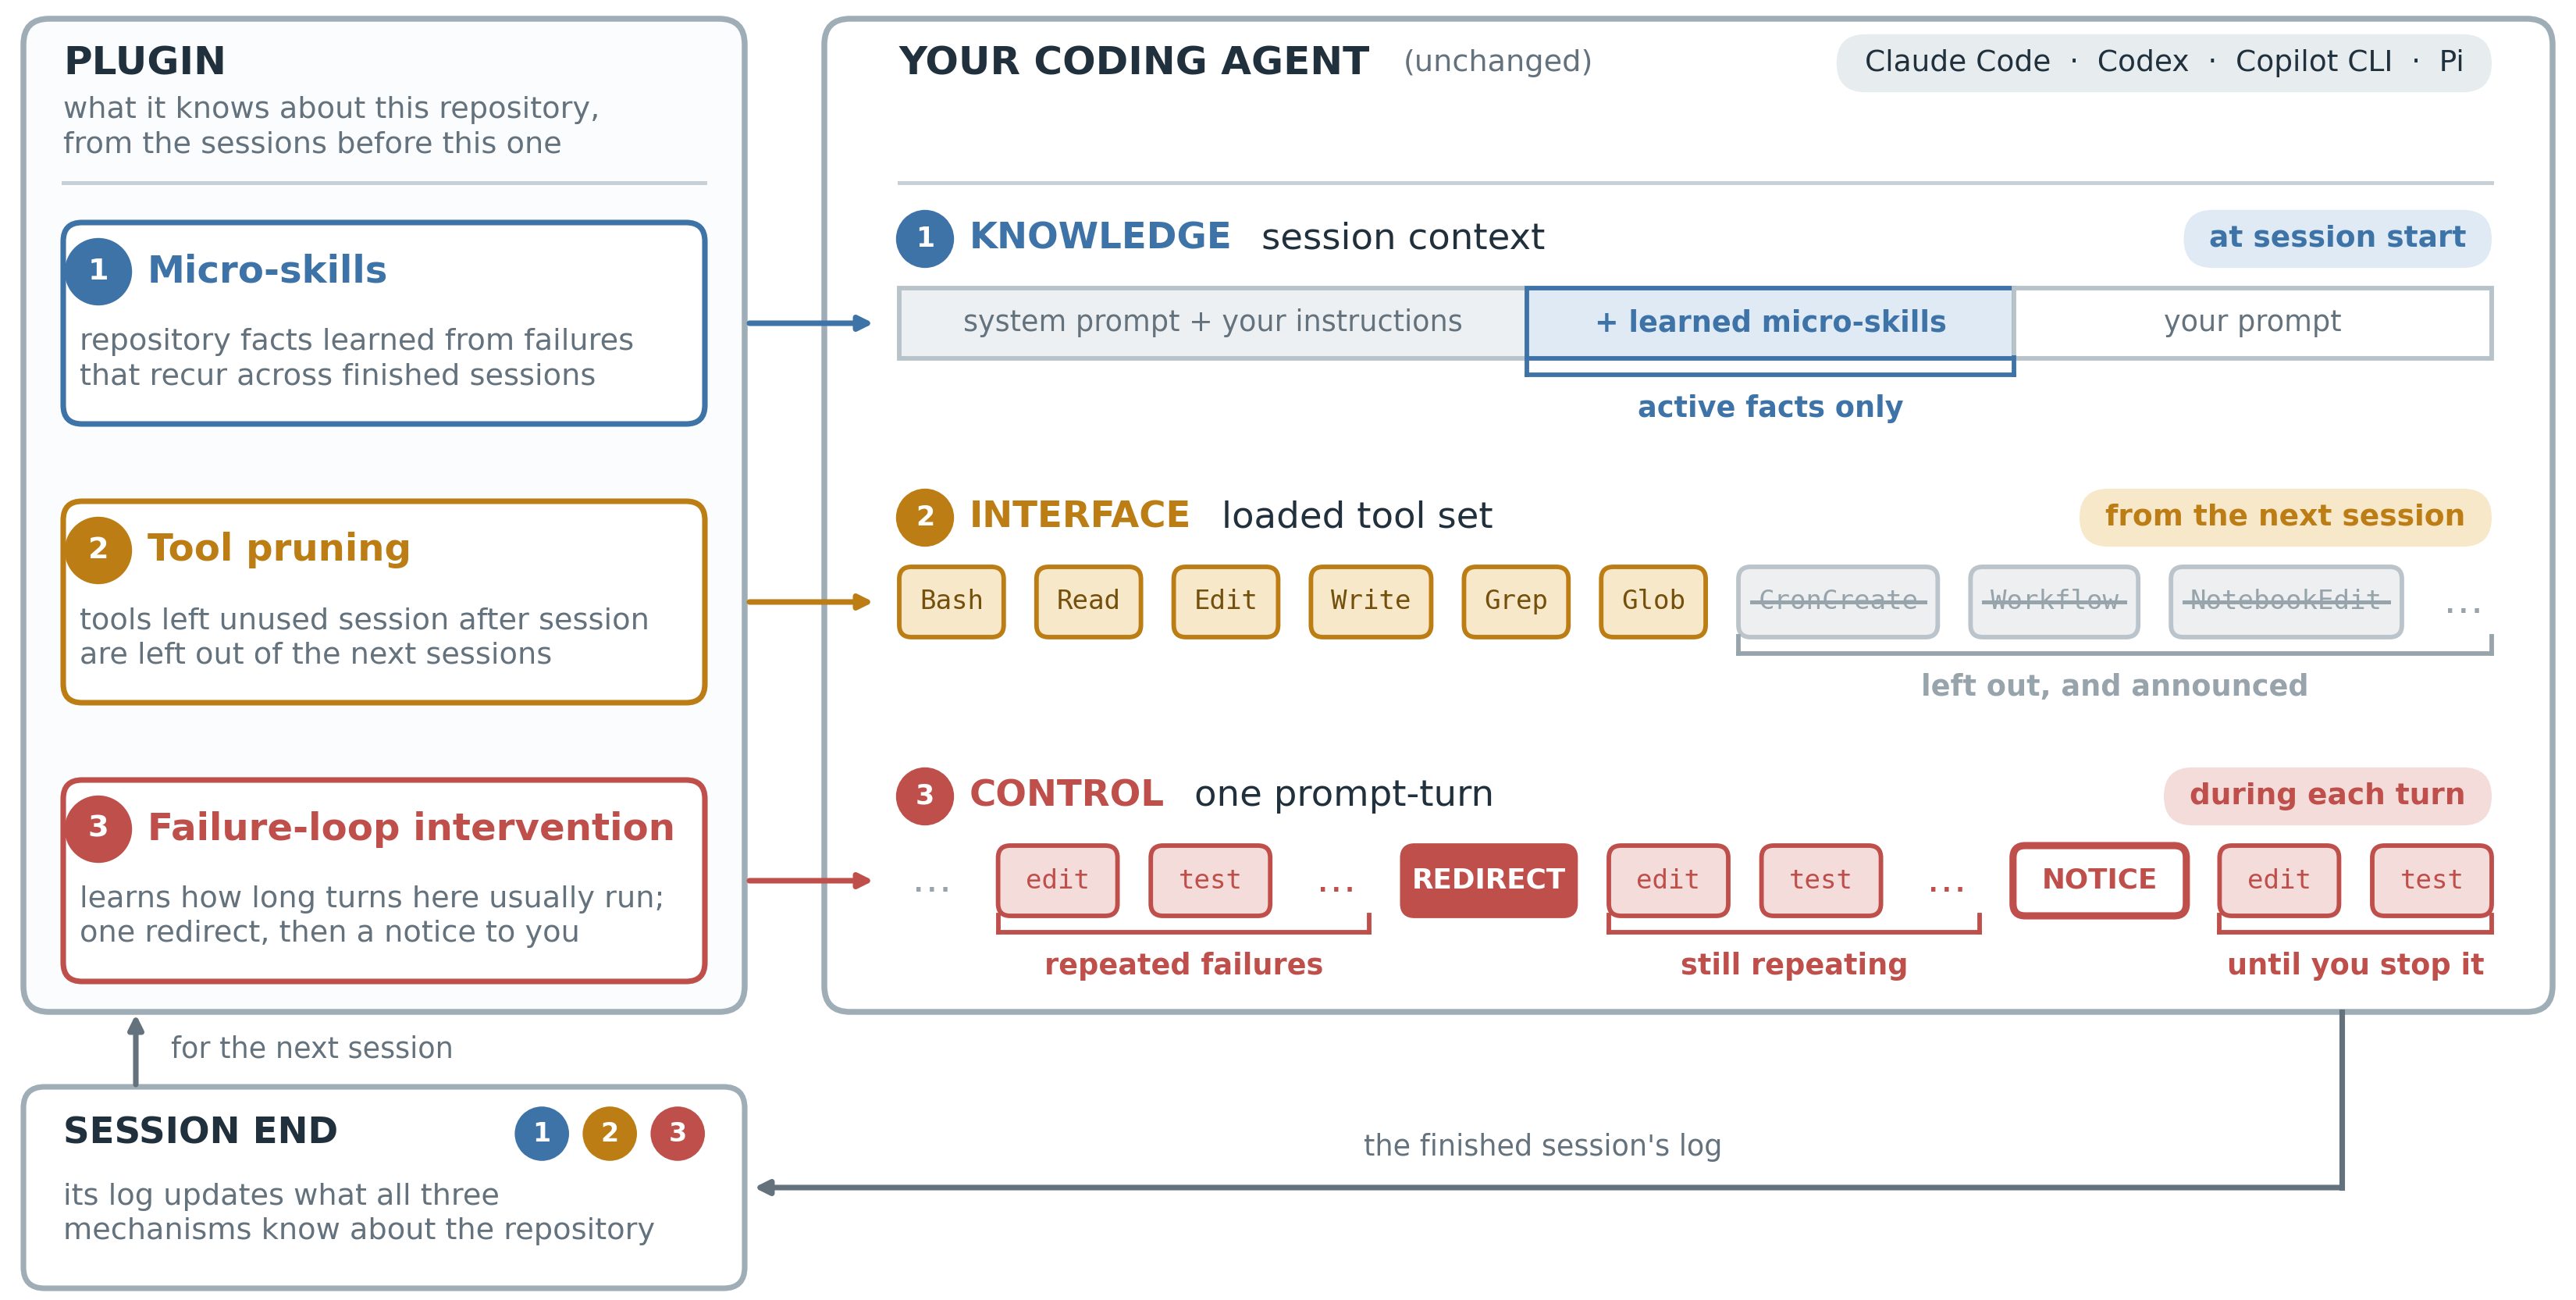
`tokprof run --
`tokprof shell` | Linux, macOS, Windows | Yes (starts child process) | Routes `OPENAI_BASE_URL`, `ANTHROPIC_BASE_URL`, `AZURE_OPENAI_ENDPOINT`, and pattern-matched `*_BASE_URL` / `*_ENDPOINT` variables through `127.0.0.1`, plus Python (`httpx`, `requests`, `urllib3`, `aiohttp`, `urllib.request`) and Node (`fetch`, `http`, `https`) hooks for clients that hard-code URLs. | | **Linux eBPF tap** | `tokprof start`
`tokprof ebpf --comm
`tokprof ebpf --pid
`tokprof pull --app-insights
`tokprof import
Python/Node hooks: **32 MB** (`_CAP`) | Captures full request and streaming SSE response bodies up to 32–64 MB without dropping frames. | **100% exact** | | **2. Per-Segment Stored Preview Cap** | **32,768 chars** per segment (`MAX_SEGMENT_TEXT_CHARS`) | Token count (`tokens`), character length (`chars`), and salted SHA-256 fingerprint (`hash`) are computed on the **entire original text first** before capping the stored preview string (`text`) at 32,768 chars with `... [truncated, N chars total]`. | **100% exact** (tokenization happens before preview truncation) | | **3. App Insights 32 KB Property Limit** | **32 KB (32,768 B)** per `Properties` / `Message` column | • Single-pass `parse_or_repair_json` repairs JSON cut off mid-string/object and marks `... [truncated by App Insights]`.
• Setting `TOKPROF_STDOUT_LOG=1` enables the gzip+base64 `[TOKPROF_CHUNK]` bridge (20 KB per line), recovering **100 KB+ prompts with 0% loss**. | Unrepaired tail is attributed to `residual`; **100% exact** with chunk bridge | | **4. Log Analytics Query Result Limit** | **500,000 rows** or **64 MB** (`ResponsePayloadTooLarge`) | • Requests `Accept-Encoding: gzip, deflate, br` (reducing transfer size by ~97.7%).
• On `ResponsePayloadTooLarge`, automatically retries with `\| take 20000` and falls back to `AppDependencies`-only.
• Supports explicit `--limit
Terminal untruncated view: `--full-prompts` | **Yes** (secrets auto-redacted) | **Yes (7 segments + `sysfp`)** | JSONL: `1.50 MB`
HTML: `1.90 MB`
CSV: `1.17 MB` | | **2. Segment Counts Only (`no-content`)** | `--no-content` or `TOKPROF_NO_CONTENT=1` | **No (`0 chars`)** | **Yes (100% identical tokens & `sysfp` hashes)** | JSONL: `384 KB` (**-74.4%**)
HTML: `245 KB` (**-87.1%**)
CSV: `25.6 KB` (**-97.8%**) | | **3. Totals Only (`usage-only`)** | `tokprof pull --usage-only`
`tokprof import --usage-only` | **No (`0 chars`, `AppTraces` not queried)** | **No** (total input/output, cost, latency, and turn curve only) | JSONL: `138 KB` (**-90.8%**)
HTML: `186 KB` (**-90.2%**)
CSV: `27.8 KB` (**-97.6%**) | ```bash # Mode 1: Keep redacted prompt & response texts (default) and inspect full text in terminal tokprof pull --workspace
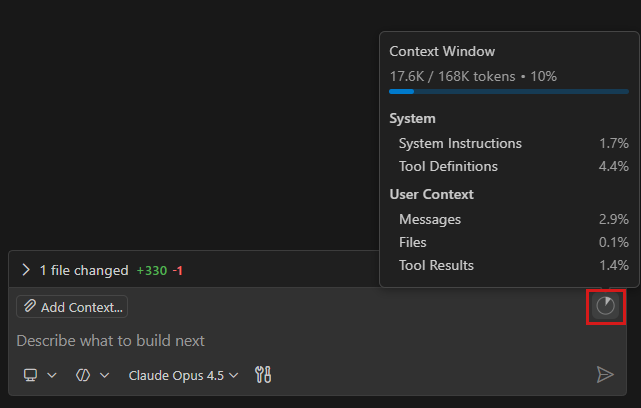
Unscoped instructions + 40 tools
100%
applyTo scoped + pruned tools
40%

5 MCP servers
100%
1 relevant server
50%
Step 1 (Call #1)
9,200 tok
Step 2 (Call #2)
13,800 tok
Step 3 (Call #3)
19,500 tok
n × prefix)가 반복 전송되고 이전 단계의 대화 기록·도구 결과(Σ)가 누적되어 입력 토큰이 늘어나는 구조. 참조: ReAct (ICLR 2022) 및 microsoft/TokenEconomizer.
English (5 tokens)
I
·met
·a
·huge
·dog
한국어 o200k_base (8 tokens)
나는
·커
다
란
·개
를
·만
났다
한국어 cl100k_base (13 tokens)
나
는
·커[1/2]
커[2/2]
다
란[1/2]
란[2/2]
·개
를
·만
났[1/2]
났[2/2]
다
tiktoken에서 같은 의미의 문장이 토큰 조각으로 나뉘는 실제 결과(·는 앞 공백 포함). cl100k_base에서는 커, 란, 났 같은 음절이 UTF-8 바이트 조각 2개로 쪼개져 13토큰이 되지만, o200k_base에서는 자주 쓰이는 한국어 음절·단어가 병합되어 8토큰으로 줄어듭니다. 출처: openai/tiktoken, OpenAI Tokenizer, examples/count_tokens.py.
정적 접두부 유지
적중 (할인)
앞부분 변경 발생
미적중 (정가)
입력 구성100%
미사용 도구2,000 토큰/호출
run_tests 3회28,800 입력 토큰
read_file 출력4,200 출력 토큰
read_file 결과의 크기이며 필터링 여부는 로그로 확인할 수 없습니다. 단위와 범위가 달라 막대 길이는 비교 기준이 아니며, 28,800은 전부 절약 가능한 양이 아닙니다. 원인이 겹칠 수 있으므로 합산하지 마세요.5단계77%
10단계60%
20단계36%
접두부 유지CACHE HIT
전체 재작성CACHE MISS
기준선39,200 입력 토큰
개선 가정약 15,200 입력 토큰
1단계 (결정적)
즉시 판정
2단계 (루브릭)
정밀 검증
`view_order_history` | `5월 10일`
`무선 이어폰`
`4567891230` | `한진택배`
`배송 중\|배송중` | `U002`의 5월 10일 무선 이어폰 주문이 한진택배(`4567891230`)로 배송 중임을 안내 | | **`HF-ECOM5-T2`** (2/5) | `iamjoon/ecommerce-...` (`train[5]`) | `hybrid`
`view_user_profile` | `Gold`
`10%` | `할인 쿠폰\|쿠폰` | 1턴의 `U002` 문맥을 유지해 `Gold` 등급 및 `10%` 할인 쿠폰 보유 사실을 안내 | | **`HF-ECOM5-T3`** (3/5) | `iamjoon/ecommerce-...` (`train[5]`) | `hybrid`
`search_policy_info` | `7일`
`왕복 배송비` | `수령 후\|수령일`
`고객센터\|신청` | 상품 수령 후 `7일` 이내 환불 신청 가능 조건과 왕복 배송비 규정을 안내 | | **`HF-ECOM5-T4`** (4/5) | `iamjoon/ecommerce-...` (`train[5]`) | `hybrid`
`search_policy_info` | `반품` | `출고되기 전\|출고 전`
`출고 이후\|출고 후`
`주문취소 버튼\|주문내역` | 출고 전에는 주문내역에서 즉시 취소 가능하고 출고 후에는 반품으로 처리됨을 구분 설명 | | **`HF-ECOM5-T5`** (5/5) | `iamjoon/ecommerce-...` (`train[5]`) | `intent_only`
*(도구 없음)* | `담당자` | `직접 처리할 수 없\|직접 처리 불가`
`전달` | AI 상담사가 직접 결제 취소할 권한이 없음을 밝히고 담당자에게 전달해 처리하겠다고 안내 | | **`HF-ECOM2-T1`** (1/4) | `iamjoon/ecommerce-...` (`train[2]`) | `hybrid`
`show_cart` | `블루투스 이어폰`
`무선 마우스` | `1개;2개` | `U001` 장바구니에 블루투스 이어폰 1개와 무선 마우스 2개가 담겨 있음을 안내 | | **`HF-ECOM2-T2`** (2/4) | `iamjoon/ecommerce-...` (`train[2]`) | `hybrid`
`view_order_history`
`view_order_details` | `고성능 노트북`
`1,150,000원` | `1대;구매` | 1턴의 `U001`을 기억해 주문 이력·상세(`O102`)를 연쇄 호출하고 고성능 노트북(`1,150,000원`) 확인 | | **`HF-ECOM2-T3`** (3/4) | `iamjoon/ecommerce-...` (`train[2]`) | `intent_only`
*(도구 없음)* | `담당자` | `기술적인 지원\|기술 지원`
`전달` | 노트북 전원 꺼짐 증상이 기술 지원 대상임을 안내하고 담당 부서 전달 약속 | | **`HF-ECOM2-T4`** (4/4) | `iamjoon/ecommerce-...` (`train[2]`) | `hybrid`
*(도구 없음)* | `카드 영수증`
`담당자` | `직접 처리할 수 없\|직접 처리 불가`
`전달` | 카드 영수증 발급은 직접 처리 불가함을 밝히고 담당자에게 전달하겠다고 안내 | | **`HF-DELIV-T1`** (1/1) | [`jjun123/delivery-app-...`](https://huggingface.co/datasets/jjun123/delivery-app-function-calling-datasets-korean) (`train[0]`) | `hybrid`
`create_delivery_order` | `14,900원;7,000원`
`21,900원;이서준`
`e2a4b1c9-...` | `관악구 관악로 1`
`준비 중\|준비중`
`담당자` | 품목·총액(`21,900원`), 수령인(`이서준`), 주문 UUID, 매장 준비 중 안내 및 도착 시간 담당자 전달 | | **`HF-DFM14-T1`** (1/1) | [`schneiderkamplab/dfm14-...`](https://huggingface.co/datasets/schneiderkamplab/dfm14-ko-synthetic-tool-dialogue-r1) (`train[2]`) | `keyword_only`
`lookup_parcel`
`redirect_parcel` | `parcel-610`
`locker-16`
`redirect-610` | `변경 처리가 완료\|변경 완료` | `tracking-610` 조회로 `parcel-610` 확인 후 `locker-16` 보관함 변경 및 `redirect-610` 반환 | | **`HF-CLINIC-T1`** (1/1) | `schneiderkamplab/dfm14-...` (`train[11]`) | `hybrid`
*(도구 없음)* | `병원 이름`
`서비스 종류` | `희망 날짜\|희망하는 날짜`
`모의 서비스\|가상`
`예약 가능 시간대` | 실제 예약 확정·의료 상담을 하지 않는 가상 모의 서비스임을 밝히고 시간대 조회만 가능함을 안내 | | **`HF-KLAC-T1`** (1/1) | [`jihye-moon/klac_legal_aid...`](https://huggingface.co/datasets/jihye-moon/klac_legal_aid_counseling) (`train[1]`) | `hybrid`
*(도구 없음)* | `제34조;제4조`
`1년;4주;15시간` | `근로기준법`
`근로자퇴직급여 보장법`
`퇴직연금` | 근로기준법 제34조·퇴직급여법 제4조 및 `1년 미만`·`4주 평균 주 15시간 미만` 제외 요건 제시 | | **`HF-KLAC-T2`** (1/1) | `jihye-moon/klac_legal_aid...` (`train[0]`) | `hybrid`
*(도구 없음)* | `최저임금법`
`제6조;무효;90%` | `3월\|3개월`
`수습` | 최저임금 미달 합의 무효(제6조) 및 수습 `3개월` 이내 최저임금 `90%` 지급 가능 요건 설명 | | **`HF-LABOR-T1`** (1/1) | [`seventy4/labor-counsel-qa`](https://huggingface.co/datasets/seventy4/labor-counsel-qa) (`train[34]`) | `hybrid`
*(도구 없음)* | `30일;30일분`
`통상임금;3개월` | `천재·사변\|부득이한 사유`
`예외` | `30일` 전 해고예고 또는 `30일분` 이상 통상임금 지급 의무와 `3개월` 미만·`천재·사변` 예외 안내 | | **`HF-OSCE-T1`** (2/2) | [`nwirandx/Korean-OSCE-...`](https://huggingface.co/datasets/nwirandx/Korean-OSCE-history-taking-dialogues) (`sessions[0..9]`) | `hybrid`
*(도구 없음)* | `김서현`
`1984년 5월 23일`
`20일;15분;20분;30분` | `과거력 없음\|과거력은 없`
`어지럽고\|어지러움`
`숨이 차\|호흡곤란` | 1~9턴 문진 내역(환자 정보, 20일 전 발병, 15~20분→30분 이상 악화, 과거력 없음, 동반 증상) 요약 | --- ## 4. 루브릭(Rubric) 평가 항목 재검토 및 설계 (5개 축 × 0·1·2점 = 10점 만점) 단일 0~10점 자유 척도는 채점 모델(LLM-as-a-Judge)이 실행할 때마다 점수가 흔들립니다. 반면 에이전트의 실패 원인을 **5개의 독립된(Orthogonal) 평가 축 × 각 0·1·2점 = 총 10점 만점**으로 분리하면, **현재 턴의 수치/슬롯 왜곡(축 2)**과 **이전 턴의 멀티턴 문맥 망각(축 3)**, 그리고 **도구 호출 및 정책 위반(축 4)**을 섞이지 않게 정확히 진단할 수 있습니다. | 평가 축 (5 Axes × 2점 = 10점 만점) | 0점 (Fail — 치명적 결함) | 1점 (Partial — 부분 충족) | 2점 (Pass — 완전 충족) | 왜 이 항목이 필요한가? | |---|---|---|---|---| | **1. 질문 의도 및 핵심 결론 정확성**
(`intent_and_resolution`) | 질문 의도를 오해했거나 `expected_intent`와 반대·무관한 결론을 냄 | 의도는 파악했으나 핵심 결론이나 필요한 후속 조치 안내가 일부 빠짐 | 표현 방식과 무관하게 `expected_intent`의 핵심 결론과 해결책을 정확히 제시함 | 단어 선택이 달라도 의미·결론이 맞는지 평가 (`intent_only` / `hybrid`) | | **2. 필수 사실·슬롯 및 수치 정확성**
(`fact_and_slot_accuracy`) | 필수 식별자·수치·법조문을 누락·왜곡했거나 없는 사실(환각)을 지어냄 | 주요 사실은 맞으나 부차적 수치·조건 표현이 모호하거나 일부 빠짐 | 모든 필수 키워드·수치·식별자·법조문을 왜곡이나 환각 없이 정확히 반영함 | 프롬프트/출력 압축 시 숫자·ID·법조문 손실 감시 (`keyword` / `hybrid`) | | **3. 멀티턴 문맥 및 상태 유지력**
(`multiturn_context_retention`) | 이전 턴(`prior_turns_context`)의 제약·식별자를 잊어 모순되거나 재질문함 | 이전 턴 정보를 일부만 반영하거나 문맥 연결이 불완전함 | 이전 턴에서 누적된 고객 ID·제약 조건·대화 상태를 누락 없이 일관되게 유지함 | 컨텍스트 압축(`/compact`)·관찰 마스킹 후 멀티턴 기억 유지 검증 | | **4. 도구 선택 및 정책·가드레일 준수**
(`tool_and_policy_compliance`) | 필수 도구를 호출하지 않고 결과를 지어내거나 금지어(`must_not_include`)·권한 밖 약속 수행 | 안전·정책 한계는 지켰으나 불필요한 도구를 중복 호출했거나 형식 제약을 어김 | 필요한 도구만 정확히 호출(권한 밖 작업은 담당자 전달)하고 모든 정책·금지 조건 준수 | 도구 가지치기 및 정책 프롬프트 축소 후 안전성·함수 호출 검증 | | **5. 간결한 완결성 (길이 편향 방지)**
(`concise_completeness`) | 필수 설명이 지나치게 생략되어 사용자가 재질문해야 하거나 문장이 깨짐 | 필요한 정보는 담겼으나 불필요한 인사말·사과·질문 되풀이로 토큰을 낭비함 | **필수 사실과 의도를 모두 충족하면서 군더더기 없이 간결하고 명확함 (짧은 답변 만점)** | **LLM Judge의 긴 답변 선호 편향(Verbosity Bias) 차단** | > **권장 통과 기준**: 1단계 결정적 검사(`must_include_all`, `must_include_any`, `must_not_include`, `expected_tools`)를 모두 통과하고, 2단계 루브릭 5개 축 합계가 **8점 이상(10점 만점)**이며 **어느 한 축도 `0점`이 아닐 때** 최종 `PASS`로 판정합니다. --- ## 5. 엑셀(`.xlsx` / `.csv`) 생성 및 하이브리드 채점 파이썬 코드 [`examples/golden_dataset_tool.py`](https://github.com/dotnetpower/agent-tokenomics/blob/main/examples/golden_dataset_tool.py)는 외부 패키지 설치 없이 표준 라이브러리만으로 **2개 시트(`Golden_Dataset`, `Rubric_Criteria` 10점 만점 기준표)와 헤더 서식·열 너비가 적용된 실제 엑셀 파일([`examples/sample-golden-dataset.xlsx`](https://github.com/dotnetpower/agent-tokenomics/raw/main/examples/sample-golden-dataset.xlsx))** 및 [`examples/sample-golden-dataset.csv`](https://github.com/dotnetpower/agent-tokenomics/blob/main/examples/sample-golden-dataset.csv)를 생성하고, `.xlsx` 또는 `.csv`를 직접 읽어 16개 Hugging Face 케이스를 평가합니다. ```bash # 1. 2개 시트(Golden_Dataset + Rubric_Criteria 10점 만점 기준표)가 포함된 실제 .xlsx 및 .csv 생성 python3 examples/golden_dataset_tool.py --write-sample # 2. 생성된 엑셀(.xlsx) 파일을 직접 읽어 Baseline vs Candidate 하이브리드 채점 실행 python3 examples/golden_dataset_tool.py --eval examples/sample-golden-dataset.xlsx # 3. 특정 멀티턴 케이스(HF-ECOM5-T5)의 10점 만점 LLM-as-a-Judge 루브릭 채점 프롬프트 출력 python3 examples/golden_dataset_tool.py --print-judge-prompt HF-ECOM5-T5 ``` ### 실제 실행 결과 (`examples/sample-golden-dataset.xlsx`, 16개 행) ```text case_id turn hf_dataset base_ok cand_ok base_tok cand_tok delta rubric -------------------------------------------------------------------------------------------------------- HF-ECOM5-T1 1 iamjoon/ecommerce-function-calli PASS PASS 4,200 2,350 -44.0% 10/10 HF-ECOM5-T2 2 iamjoon/ecommerce-function-calli PASS PASS 5,800 3,100 -46.6% 10/10 HF-ECOM5-T3 3 iamjoon/ecommerce-function-calli PASS PASS 7,400 3,850 -48.0% 10/10 HF-ECOM5-T4 4 iamjoon/ecommerce-function-calli PASS PASS 9,100 4,500 -50.5% 10/10 HF-ECOM5-T5 5 iamjoon/ecommerce-function-calli PASS PASS 10,800 4,950 -54.2% 10/10 HF-ECOM2-T1 1 iamjoon/ecommerce-function-calli PASS PASS 4,100 2,200 -46.3% 10/10 HF-ECOM2-T2 2 iamjoon/ecommerce-function-calli PASS PASS 6,900 3,600 -47.8% 10/10 HF-ECOM2-T3 3 iamjoon/ecommerce-function-calli PASS PASS 8,300 4,100 -50.6% 10/10 HF-ECOM2-T4 4 iamjoon/ecommerce-function-calli PASS PASS 9,600 4,450 -53.6% 10/10 HF-DELIV-T1 1 jjun123/delivery-app-function-ca PASS PASS 12,400 6,800 -45.2% 10/10 HF-DFM14-T1 1 schneiderkamplab/dfm14-ko-synthe PASS PASS 5,400 2,900 -46.3% 10/10 HF-CLINIC-T1 1 schneiderkamplab/dfm14-ko-synthe PASS PASS 4,900 2,700 -44.9% 10/10 HF-KLAC-T1 1 jihye-moon/klac_legal_aid_counse PASS PASS 6,400 3,300 -48.4% 10/10 HF-KLAC-T2 1 jihye-moon/klac_legal_aid_counse PASS PASS 5,900 3,100 -47.5% 10/10 HF-LABOR-T1 1 seventy4/labor-counsel-qa PASS PASS 5,200 2,850 -45.2% 10/10 HF-OSCE-T1 2 nwirandx/Korean-OSCE-history-tak PASS PASS 9,400 4,600 -51.1% 10/10 -------------------------------------------------------------------------------------------------------- Pass rate : Baseline 16/16 (100.0%) -> Candidate 16/16 (100.0%) Mean rubric score : Baseline 9.62/10 -> Candidate 10.00/10 Total tokens : Baseline 115,800 -> Candidate 59,350 (-48.7%) Cost-of-Pass (tok) : Baseline 7,238 tok/pass -> Candidate 3,709 tok/pass Decision : KEEP (Quality held & tokens reduced) ``` --- ## 관련 연구(논문) - [Cost-of-Pass: An Economic Framework for Evaluating Language Models](https://arxiv.org/abs/2504.13359) — 프리프린트 2025. 단일 호출 비용이 아니라 성공한 작업 1건당 기대 비용(`Cost-of-Pass`)으로 모델을 평가합니다. - [$\tau$-bench: A Benchmark for Tool-Agent-User Interaction in Real-World Domains](https://arxiv.org/abs/2406.12045) — 프리프린트 2024. 멀티턴 도구 호출과 정책 준수를 반복 실행 일관성(`pass^k`)으로 평가합니다. - [AI Agents That Matter](https://arxiv.org/abs/2407.01502) — 프리프린트 2024. 에이전트 벤치마크에서 비용과 정확도를 함께 보고하고 데이터 오염을 방지하는 평가 원칙을 정리합니다. - [Adding Error Bars to Evals: A Statistical Approach to Language Model Evaluations](https://arxiv.org/abs/2411.00640) — 프리프린트 2024. 대응 표본 평가에서 신뢰구간과 표본 크기를 계산하는 방법을 다룹니다. - [LongMemEval: Benchmarking Chat Assistants on Long-Term Interactive Memory](https://arxiv.org/abs/2410.10813) — ICLR 2025. 멀티턴 대화에서 이전 턴에 심어 둔 사실 회상과 갱신 능력을 측정합니다. --- ## 사례 연구: TokenEconomizer (ko/agent-tokenomics/case-tokeneconomizer.md) Canonical URL:
저장소 사실
도구 선택
실패 대응
`tokprof run --
`tokprof shell` | Linux, macOS, Windows | 필요 (`tokprof`가 하위 프로세스 시작) | `OPENAI_BASE_URL`, `ANTHROPIC_BASE_URL`, `AZURE_OPENAI_ENDPOINT` 및 패턴으로 찾은 `*_BASE_URL` / `*_ENDPOINT` 변수를 `127.0.0.1` 게이트웨이로 라우팅하고, 엔드포인트를 하드코딩한 클라이언트를 위해 Python(`httpx`, `requests`, `urllib3`, `aiohttp`, `urllib.request`) 및 Node(`fetch`, `http`, `https`) 훅을 함께 로드합니다. | | **Linux eBPF 탭** | `tokprof start`
`tokprof ebpf --comm <이름>`
`tokprof ebpf --pid
`tokprof pull --app-insights
`tokprof import <파일>` | 모든 OS 및 **Azure Cloud Shell** | **불필요** (수집된 텔레메트리 조회) | `AppDependencies`와 `AppTraces`(OpenTelemetry GenAI, OpenInference, APIM, 또는 `[TOKPROF_CHUNK]` 로그)를 조인해 프롬프트·도구 스키마를 역조립하고 7대 세그먼트 분해 또는 Usage-Only 폴백 리포트를 생성합니다. | --- ## 4. 리포트 조회, HTML 대시보드, CSV 내보내기 및 전후 비교 측정이 끝나면 타임스탬프가 붙은 JSONL 로그가 저장되고 `.tokprof/latest.html`이 갱신됩니다. ```bash # .tokprof/에 기록된 가장 최근 실행의 터미널 요약 리포트 출력 tokprof report # 잘림 없이 전체 프롬프트와 응답 원문을 터미널에 출력 tokprof report --full-prompts # 단일 파일 HTML 대시보드(.tokprof/latest.html) 생성 및 브라우저 열기 tokprof report --html --open # 세션별·턴별·호출별 토큰 분해와 프롬프트 원문을 CSV로 저장 tokprof report --format csv --out run.csv tokprof report --csv # 에이전트 실행 중 1초 간격으로 갱신되는 실시간 터미널 대시보드 tokprof report --watch # 사용자 정의 가격표(1M 토큰당 단가)를 적용해 예상 비용 계산 tokprof report --prices prices.json # 최적화 전(before)과 후(after) 두 실행을 95% 부트스트랩 신뢰구간으로 비교 (3단계·5단계) tokprof compare before.jsonl after.jsonl ``` ### HTML 및 CLI 리포트에서 확인할 수 있는 정보 1. **입력 토큰 상세 분해(Input token breakdown)**: 시스템 프롬프트(마크다운 제목 및 XML 태그 단위 분할), 도구 정의, 도구 결과, 도구 호출, 대화 이력(이전 사용자·어시스턴트 턴), 현재 사용자 프롬프트(`utterance`, `context`/`history`, `capabilities` 구조화 JSON 페이로드 자동 분리 포함), 응답 스키마, 미분류 템플릿 오버헤드 비중을 보여 줍니다. 2. **세션별·턴별 흐름(Per-Session & Per-Turn lineage)**: 고정 접두부 토큰, 대화 이력 누적, 캐시 적중률, 턴당 호출 수(`calls/turn`)가 턴이 진행됨에 따라 어떻게 변하는지 시각화합니다. 3. **프롬프트 및 도구 스키마 원문 뷰어(Call & Turn Prompt Dossier)**: 각 턴과 개별 호출에서 실제로 전송된 시스템 프롬프트, 대화 이력, 사용자 프롬프트, 도구 스키마, 모델 응답 원문을 확인할 수 있습니다. 4. **자동 진단 결과(Findings & recommendations)**: 호출되지 않은 도구 정의, 동일한 도구 호출·오류가 반복되는 실패 루프, 시스템 프롬프트 내 동적 값으로 인한 프롬프트 캐시 깨짐, 급격한 대화 이력 증가를 자동으로 감지하고 해당하는 트랙 B 단계로 안내합니다. --- ## 5. 사내·온프레미스 엔드포인트 및 프라이버시 ### 사내 DNS, vLLM, Ollama, TGI, LiteLLM 및 사설 CA 인증서 `tokprof`는 고정된 도메인 목록에 의존하지 않고 요청 본문 구조, URL 경로, 호스트·포트 힌트, 응답 사용량 필드를 종합해 점수를 매깁니다. ```bash # 특정 URL과 요청 본문 JSON이 LLM 호출로 분류되는지 점수와 판정 이유 확인 tokprof explain http://vllm.internal:8000/v1/chat/completions --body request.json # 특정 호스트·경로를 강제로 포함하거나 사내 CA 인증서를 신뢰하도록 지정 tokprof start --llm-host 'gpu*.corp' --llm-path '/internal/ask$' --upstream-ca corp-ca.pem tokprof run --exclude-host telemetry.corp -- python my_agent.py ``` ### 프라이버시 및 마스킹 - **저장하지 않는 항목**: HTTP 헤더(`Authorization`, `x-api-key`)와 API 키는 절대 기록하지 않습니다. - **파일 권한**: `.tokprof/` 아래의 모든 파일은 `0600`(소유자만 읽기·쓰기) 권한으로 생성됩니다. - **프롬프트 원문 제외**: `--no-content`(`tokprof start --no-content` 또는 `tokprof run --no-content -- ...`)를 지정하면 프롬프트·응답 원문을 저장하지 않고 토큰 수, 길이, 솔트 처리된 SHA-256 해시만 기록합니다. --- ## 6. 이미 Azure에 배포된 에이전트 프로파일링 (Cloud Shell & Application Insights) 이미 Azure에 배포되어 운영 중인 에이전트의 경우, 커널 수준 eBPF(`CAP_BPF`)는 Linux VM이나 특권(privileged) AKS 노드에서만 사용할 수 있습니다. App Service, Container Apps(ACA), Azure Functions, Foundry Hosted Agent 같은 관리형 PaaS/Serverless 환경을 위해 `tokprof`는 `tokprof pull`, `tokprof import`, 그리고 무손실 청크 로그 브리지(`TOKPROF_STDOUT_LOG=1`)를 제공합니다. ### Azure 호스팅 환경별 가능 / 불가능 매트릭스 | Azure 호스팅 환경 | `tokprof ebpf` | `tokprof run` / 훅 주입 | `tokprof pull` / `import` (App Insights) | 권장 수집 방식 | |-------------------|----------------|-------------------------|------------------------------------------|----------------| | **Azure VM / VMSS (Linux)** | **가능 (O)** | **가능 (O)** | **가능 (O)** | SSH/Bastion 접속 후 `sudo tokprof start` (재시작 불필요) | | **AKS (Kubernetes)** | **조건부 (△)** (`CAP_BPF` 및 `/sys/kernel/btf` 필요) | **가능 (O)** | **가능 (O)** | 특권 디버그 컨테이너/DaemonSet, 사이드카 게이트웨이, 또는 `tokprof pull` | | **Azure App Service / Container Apps (ACA)** | **불가능 (X)** (커널 샌드박스 격리) | **가능 (O)** (시작 명령 또는 `PYTHONPATH` / `NODE_OPTIONS`) | **가능 (O)** | Application Insights에서 `tokprof pull` 실행 또는 `TOKPROF_STDOUT_LOG=1` 훅 | | **Azure Functions** | **불가능 (X)** | **훅만 가능 (△)** (`PYTHONPATH` / `NODE_OPTIONS`) | **가능 (O)** | Application Insights에서 `tokprof pull` 실행 또는 `TOKPROF_STDOUT_LOG=1` 훅 | | **Azure AI Foundry Hosted Agent** | **불가능 (X)** (완전 관리형 런타임) | **불가능 (X)** | **가능 (O)** | Foundry 프로젝트에 연결된 Application Insights / Log Analytics에서 `tokprof pull` 실행 | ### Azure Cloud Shell에서 `tokprof` 설치 및 실행 `tokprof`는 PyPI에 정적 빌드된 `manylinux2014_x86_64` 네이티브 바이너리 Wheel로 배포되어 있어, Azure Cloud Shell에서 Rust나 Go 컴파일러 없이 수 초 내에 설치되며 `$HOME` 영구 스토리지에 유지됩니다. ```bash # Azure Cloud Shell에 설치 pip install --user tokprof export PATH="$HOME/.local/bin:$PATH" # Log Analytics 또는 Application Insights에서 최근 6시간 LLM 호출 수집 및 분석 # (Cloud Shell의 기존 `az` 로그인 세션을 자동으로 사용합니다) tokprof pull --workspace
Python/Node 훅: **32 MB** (`_CAP`) | 최대 32~64 MB 크기의 요청 본문과 SSE 스트리밍 응답을 유실 없이 수집합니다. | **100% 정확** | | **2. 세그먼트별 저장 텍스트 상한** | 세그먼트당 **32,768 문자** (`MAX_SEGMENT_TEXT_CHARS`) | **토큰 수(`tokens`), 글자 수(`chars`), SHA-256 해시(`hash`)를 절단 전 원본 전체에 대해 먼저 계산**한 뒤, 디스크(`.jsonl`/`.html`)에 저장하는 미리보기 텍스트(`text`)만 32,768자에서 자르고 `... [truncated, N chars total]` 표시를 남깁니다. | **100% 정확** (미리보기 절단 전에 토큰 계산 완료) | | **3. App Insights 32KB 컬럼 한도** | `Properties` / `Message` 컬럼당 **32 KB (32,768 B)** | • 단일 패스 `parse_or_repair_json`이 문자열/객체 중간에서 잘린 JSON을 복구해 앞부분 세그먼트를 살리고 `... [truncated by App Insights]`를 표시합니다.
• 에이전트에 `TOKPROF_STDOUT_LOG=1`을 켜면 20KB 단위 Gzip+Base64 `[TOKPROF_CHUNK]` 브리지로 **100KB+ 대형 프롬프트도 손실 0%로 복원**합니다. | 기본 로깅 시 절단 이후 구간은 `residual`로 귀속 / 청크 브리지 사용 시 **100% 정확** | | **4. Log Analytics 쿼리 결과 한도** | 단일 쿼리당 **500,000 행** 또는 **64 MB** (`ResponsePayloadTooLarge`) | • `Accept-Encoding: gzip, deflate, br`로 응답을 수신해 네트워크 전송 크기를 **약 97.7% 축소**합니다.
• `ResponsePayloadTooLarge` 발생 시 자동으로 `\| take 20000` 상한을 붙여 재시도하고, 그래도 초과하면 `AppDependencies` 전용 쿼리로 안전하게 폴백합니다.
• `--limit <행수>` 및 `--usage-only` 수동 제한도 지원합니다. | 안전 폴백으로 쿼리 실패 방지 | #### 프롬프트 원문 포함 / 제외 3단계 제어 모드 보안 정책이나 파일 크기 제약에 따라 **수집(`pull`/`start`/`run`) · 변환(`import`) · 리포트(`report`) 모든 단계**에서 프롬프트 포함 여부를 3단계로 선택할 수 있습니다. | 제어 모드 | CLI 플래그 / 환경변수 | 디스크에 프롬프트 원문 저장 여부 | 7대 세그먼트 분해 및 `sysfp` 해시 | 생성 파일 크기 실측치 (200 호출 / 1,400 세그먼트 기준) | |-----------|-----------------------|----------------------------------|-----------------------------------|--------------------------------------------------------| | **1. 프롬프트 포함 (`full-prompts`)** | *(기본값)*
터미널 전체 출력: `--full-prompts` | **저장함 (O)** (시크릿 자동 마스킹) | **지원 (7대 세그먼트 + `sysfp`)** | JSONL: `1.50 MB`
HTML: `1.90 MB`
CSV: `1.17 MB` | | **2. 세그먼트 분해만 유지 + 원문 제거 (`no-content`)** | `--no-content` 또는 `TOKPROF_NO_CONTENT=1` | **저장 안 함 (`0자`)** | **지원 (모드 1과 토큰·해시 100% 동일)** | JSONL: `384 KB` (**-74.4%**)
HTML: `245 KB` (**-87.1%**)
CSV: `25.6 KB` (**-97.8%**) | | **3. 총량만 수집 (`usage-only`)** | `tokprof pull --usage-only`
`tokprof import --usage-only` | **저장 안 함 (`0자`, `AppTraces` 미조회)** | **생략** (총 토큰·비용·지연 시간·턴 추이만 집계) | JSONL: `138 KB` (**-90.8%**)
HTML: `186 KB` (**-90.2%**)
CSV: `27.8 KB` (**-97.6%**) | ```bash # 모드 1: 프롬프트 및 응답 원문 포함 (기본값) + 터미널에서 생략 없이 전체 원문 출력 tokprof pull --workspace
범위 없는 지침 + 도구 40개
100%
applyTo 범위 지정 + 도구 가지치기
40%
MCP 서버 5개
100%
필요한 서버 1개
50%